Three plot types are provided:
type = "comparison"(default)A fair comparison of the candidate learners against the super learner ensemble. For each learner — candidates and
super_learneralike — bars and filled points show the mean held-out loss across the outer cross-validation folds, open circles show each outer fold's held-out loss, and ranges show \(\pm 1\) standard deviation across folds. Learners are ordered best (lowest mean loss) at top. This automates the figure shown in the package README.type = "weights"Ensemble-weight stability across the outer folds; delegated to
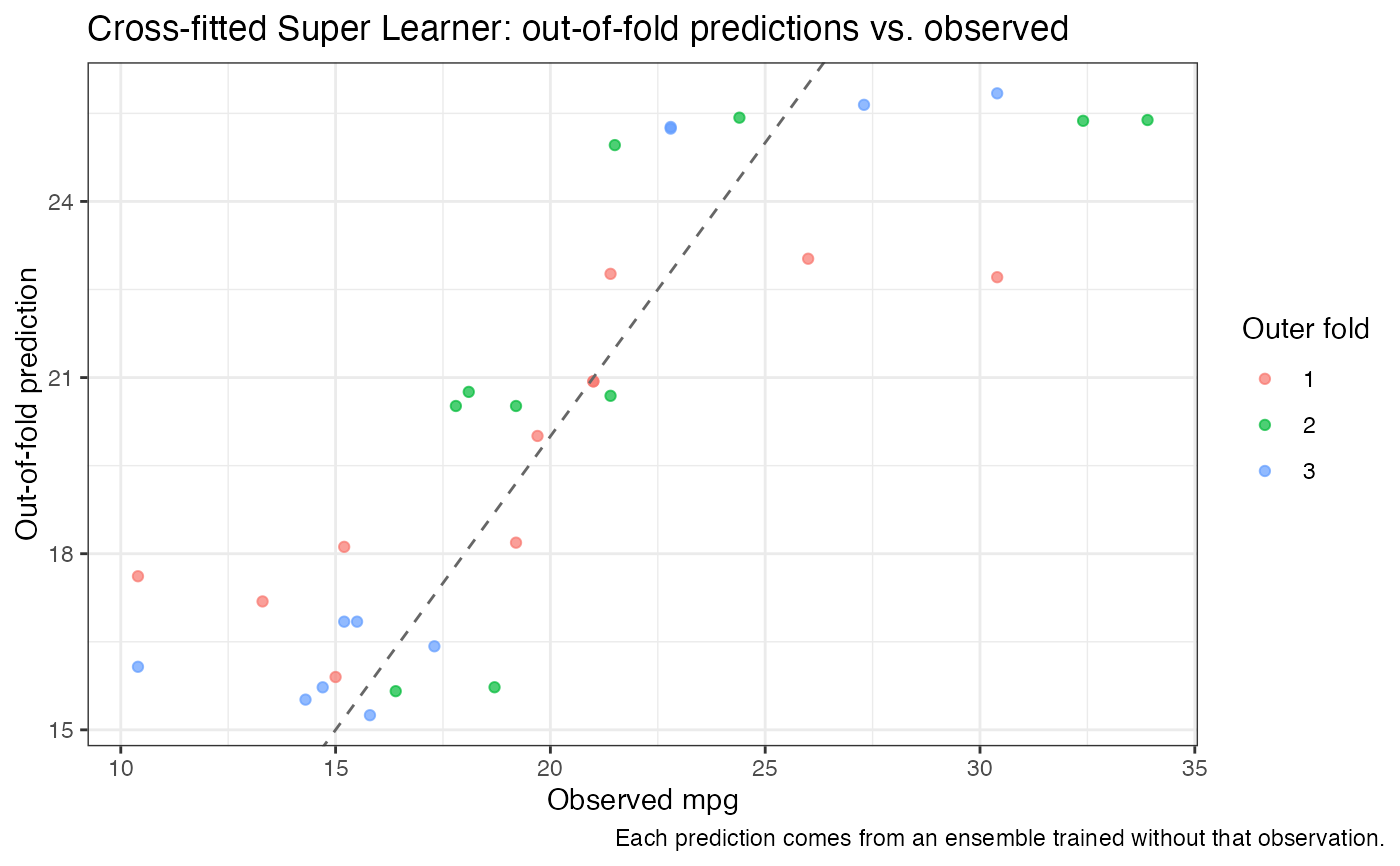
plot.nadir_crossfit_sl(x$crossfit, type = "weights").type = "fitted"Out-of-fold ensemble predictions against observed outcomes; delegated to
plot.nadir_crossfit_sl(x$crossfit, type = "fitted"). Not defined foroutcome_type = "density"or"multiclass".
Arguments
- x
An object of class
nadir_cv_slas returned bycv_super_learner().- type
One of
"comparison","weights", or"fitted".- ...
Ignored; included for compatibility with the generic.
Details
Why is this the fair comparison, rather than
plot(super_learner(...))? A super_learner() fit's ensemble
weights are chosen using its candidates' holdout predictions, so
scoring the ensemble on those same holdouts is optimistically biased —
which is why plot.nadir_sl_model deliberately omits the
ensemble from its comparison. cv_super_learner() adds the outer
layer of cross-validation needed to score the ensemble honestly, and this
plot method scores every candidate on those same outer validation
folds: within each outer fold, the candidate fits and the ensemble
weights were all estimated entirely without the validation data they are
evaluated on, and every learner is trained on the same outer training
data. All quantities are derived from the fitted object (the per-fold
super_learner() fits stored in $crossfit); nothing is
re-fit, though each candidate is re-predicted once per outer fold.
The loss is the loss_metric stored at fit time (by default, mean
squared error for continuous outcomes and negative log loss otherwise).
Learners that errored on an outer training fold contribute no loss for
that fold.
Requires the ggplot2 package (listed in Suggests).
Examples
if (requireNamespace("ggplot2", quietly = TRUE)) {
  cv_sl <- cv_super_learner(
    data = mtcars,
    formula = mpg ~ cyl + hp,
    n_folds = 3, inner_n_folds = 2,
    learners = list(mean = lnr_mean, lm = lnr_lm)
  )
  plot(cv_sl) # fair candidates-vs-ensemble comparison
  plot(cv_sl, type = "weights") # weight stability across outer folds
  plot(cv_sl, type = "fitted") # out-of-fold predictions vs. observed
}
#> The loss_metric is being inferred based on the outcome_type=continuous -> using CV-MSE